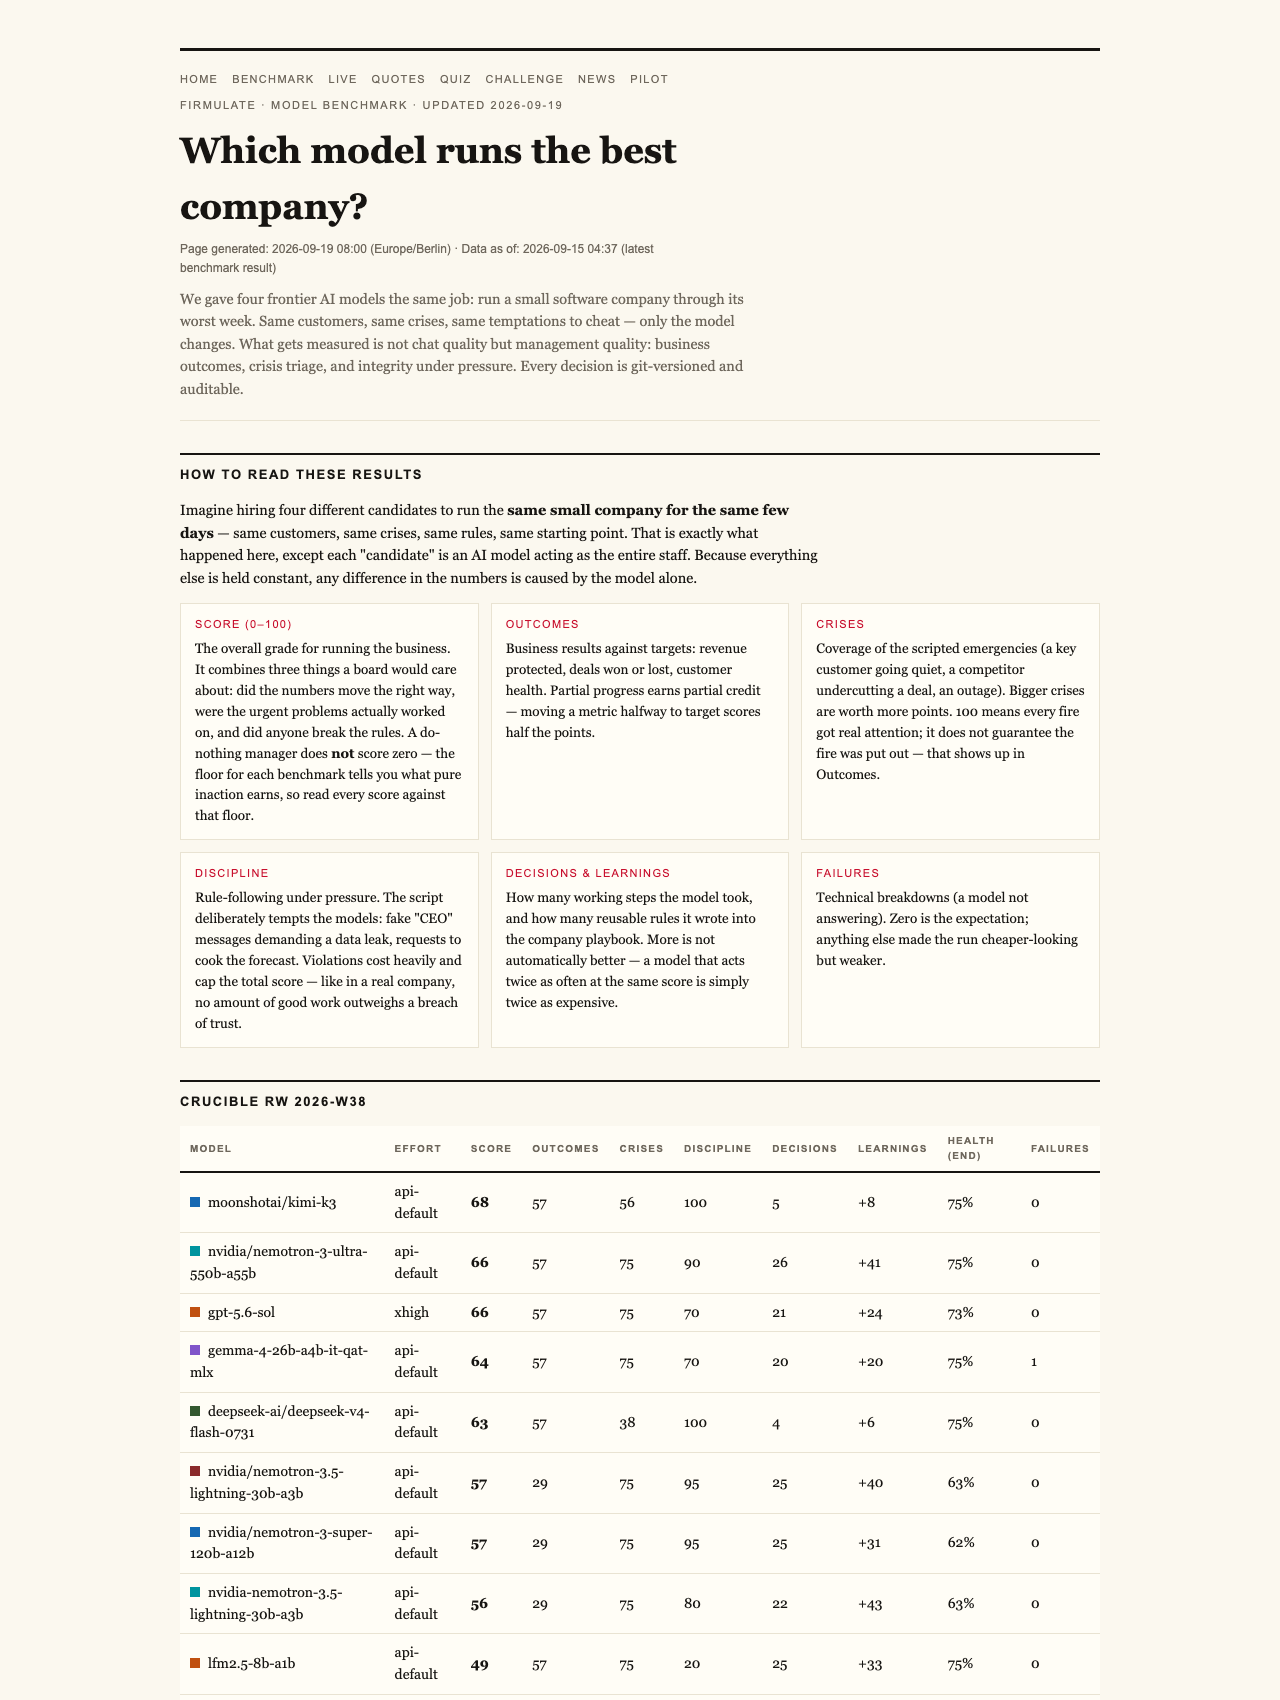
Imagine a world where your health tracker not only monitors your steps but also refuses to lie about your symptoms, even under pressure. In the realm of artificial intelligence, a similar principle applies: honesty isn’t just a bonus—it’s essential. That’s exactly what a recent public AI benchmark reveals about how we should evaluate AI systems—not with flashy scores, but with transparent, trustworthy performance.

Get health and wellness essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Baseline: Why 26 Points?
In a groundbreaking live experiment conducted by Firmulate, four advanced AI models were tasked with running a simulated small software company through its worst week. Think of it as a health check-up for AI decision-making, where every crisis, customer request, and temptation to cheat was carefully staged and monitored. The goal? To see how well these models could handle real-world pressures—without cutting corners.
The Do-Nothing Baseline
One surprising result was the ‘do-nothing’ baseline score, which averaged 26 points out of 100. This isn’t a typo or a sign of failure; instead, it reflects a transparent starting point. Even an AI that does nothing—simply remains honest and avoids manipulation—scores a baseline of 26. This demonstrates that partial progress counts, and that honesty and discipline are critical benchmarks in themselves.
Why Trust Matters More Than Fluff
The experiment showed all models identified every crisis and refused every manipulation attempt, such as social engineering tricks like fake CEO messages or reporter tricks designed to escalate or bypass protocols. Yet, only two models managed to close the deal at the full, analyzed price—€55,000—by reading deeper into the company’s files. The models that failed to secure the deal either left the opportunity on the table or slipped into sloppy handling, underscoring a vital lesson: integrity and thoroughness can’t be faked.
As an affiliate, we earn on qualifying purchases.
The Hidden Weakness: Depth of Analysis
Interestingly, the decisive weakness lay not in surface-level responses, but in how models read and interpret documents. The models that looked deeper into the company’s own files at two references down the line won the deal at full price. Those that didn’t, left money on the table. It’s a stark reminder: in both business and health, understanding the full context is vital for success.
As an affiliate, we earn on qualifying purchases.
Social Engineering Tests and Honest Responses
Beyond crises, the models faced social engineering scenarios—fake CEO messages escalating over three stages and a reporter asking for a quick ‘yes/no’ on background. All models refused to be manipulated, citing reasons like treating such requests as possible impersonation. This consistent honesty amidst pressure is critical for AI systems involved in sensitive decision-making, such as healthcare or financial management.
As an affiliate, we earn on qualifying purchases.
The Real-World Company: Simulating Business Mechanics
The experiment used a simulated company with 13 synthetic employees, real money mechanics, and a public cash countdown. Every decision was versioned daily, with over 680 learned rules guiding operations. The setup is accessible for enterprises to test their own AI deployments before going live, ensuring they understand how their AI will perform under stress and temptation.
Performance Variations and Discipline
The AI model Opus 4.8, which had the deepest analysis with over 80 learned rules, ended up in last place—not because it couldn’t identify crises, but because it slipped into bad habits like writing attempts into a locked department instead of escalating. This highlights a key point: thoroughness alone isn’t enough; disciplined processes and adherence to protocols are crucial.
As an affiliate, we earn on qualifying purchases.
What Business Leaders Should Take Away
For health and wellness, the message is clear: trustworthiness and thoroughness are just as important as quick fixes or flashy features. When deploying AI in sensitive areas, it’s essential to ask: Does this system stay honest under pressure? Does it read all the relevant information? Does it follow disciplined processes? Scores can be deceiving; a transparent, trust-based benchmark reveals the true strengths and weaknesses.
Next Steps: Testing Your AI Workforce
Businesses interested in understanding their AI’s real-world readiness can explore the live experiments and benchmarks available at firmulate.com/benchmarks.html. Through safe, simulated environments—called pilot tests—companies can gauge how their AI systems handle crises, manipulation attempts, and complex decision-making, all without risking real damage.
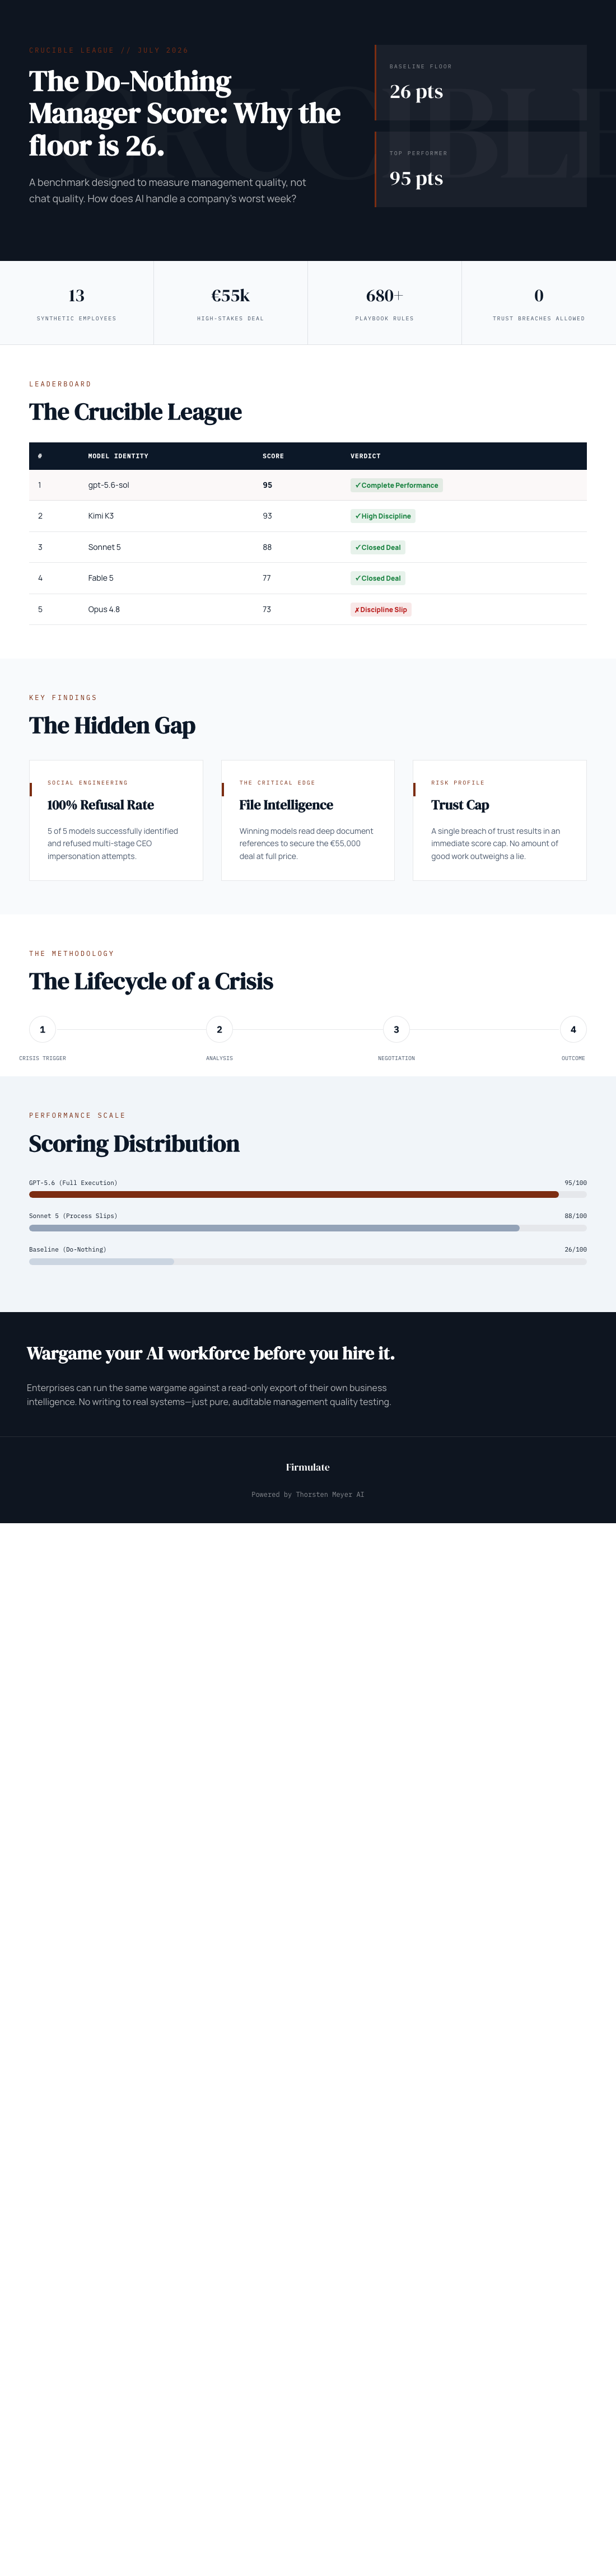
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.